Open Sources
Curated repos, tools, and frameworks shaping the developer ecosystem.
Live data from GitHub.
Curated repos, tools, and frameworks shaping the developer ecosystem.
Live data from GitHub.
by NVlabs
SANA: Efficient High-Resolution Image Synthesis with Linear Diffusion Transformer

Demo | 🎬 SANA-Video 2.0 Demo | 🤗 HuggingFace | ComfyUI | SGLang | Cosmos-RL





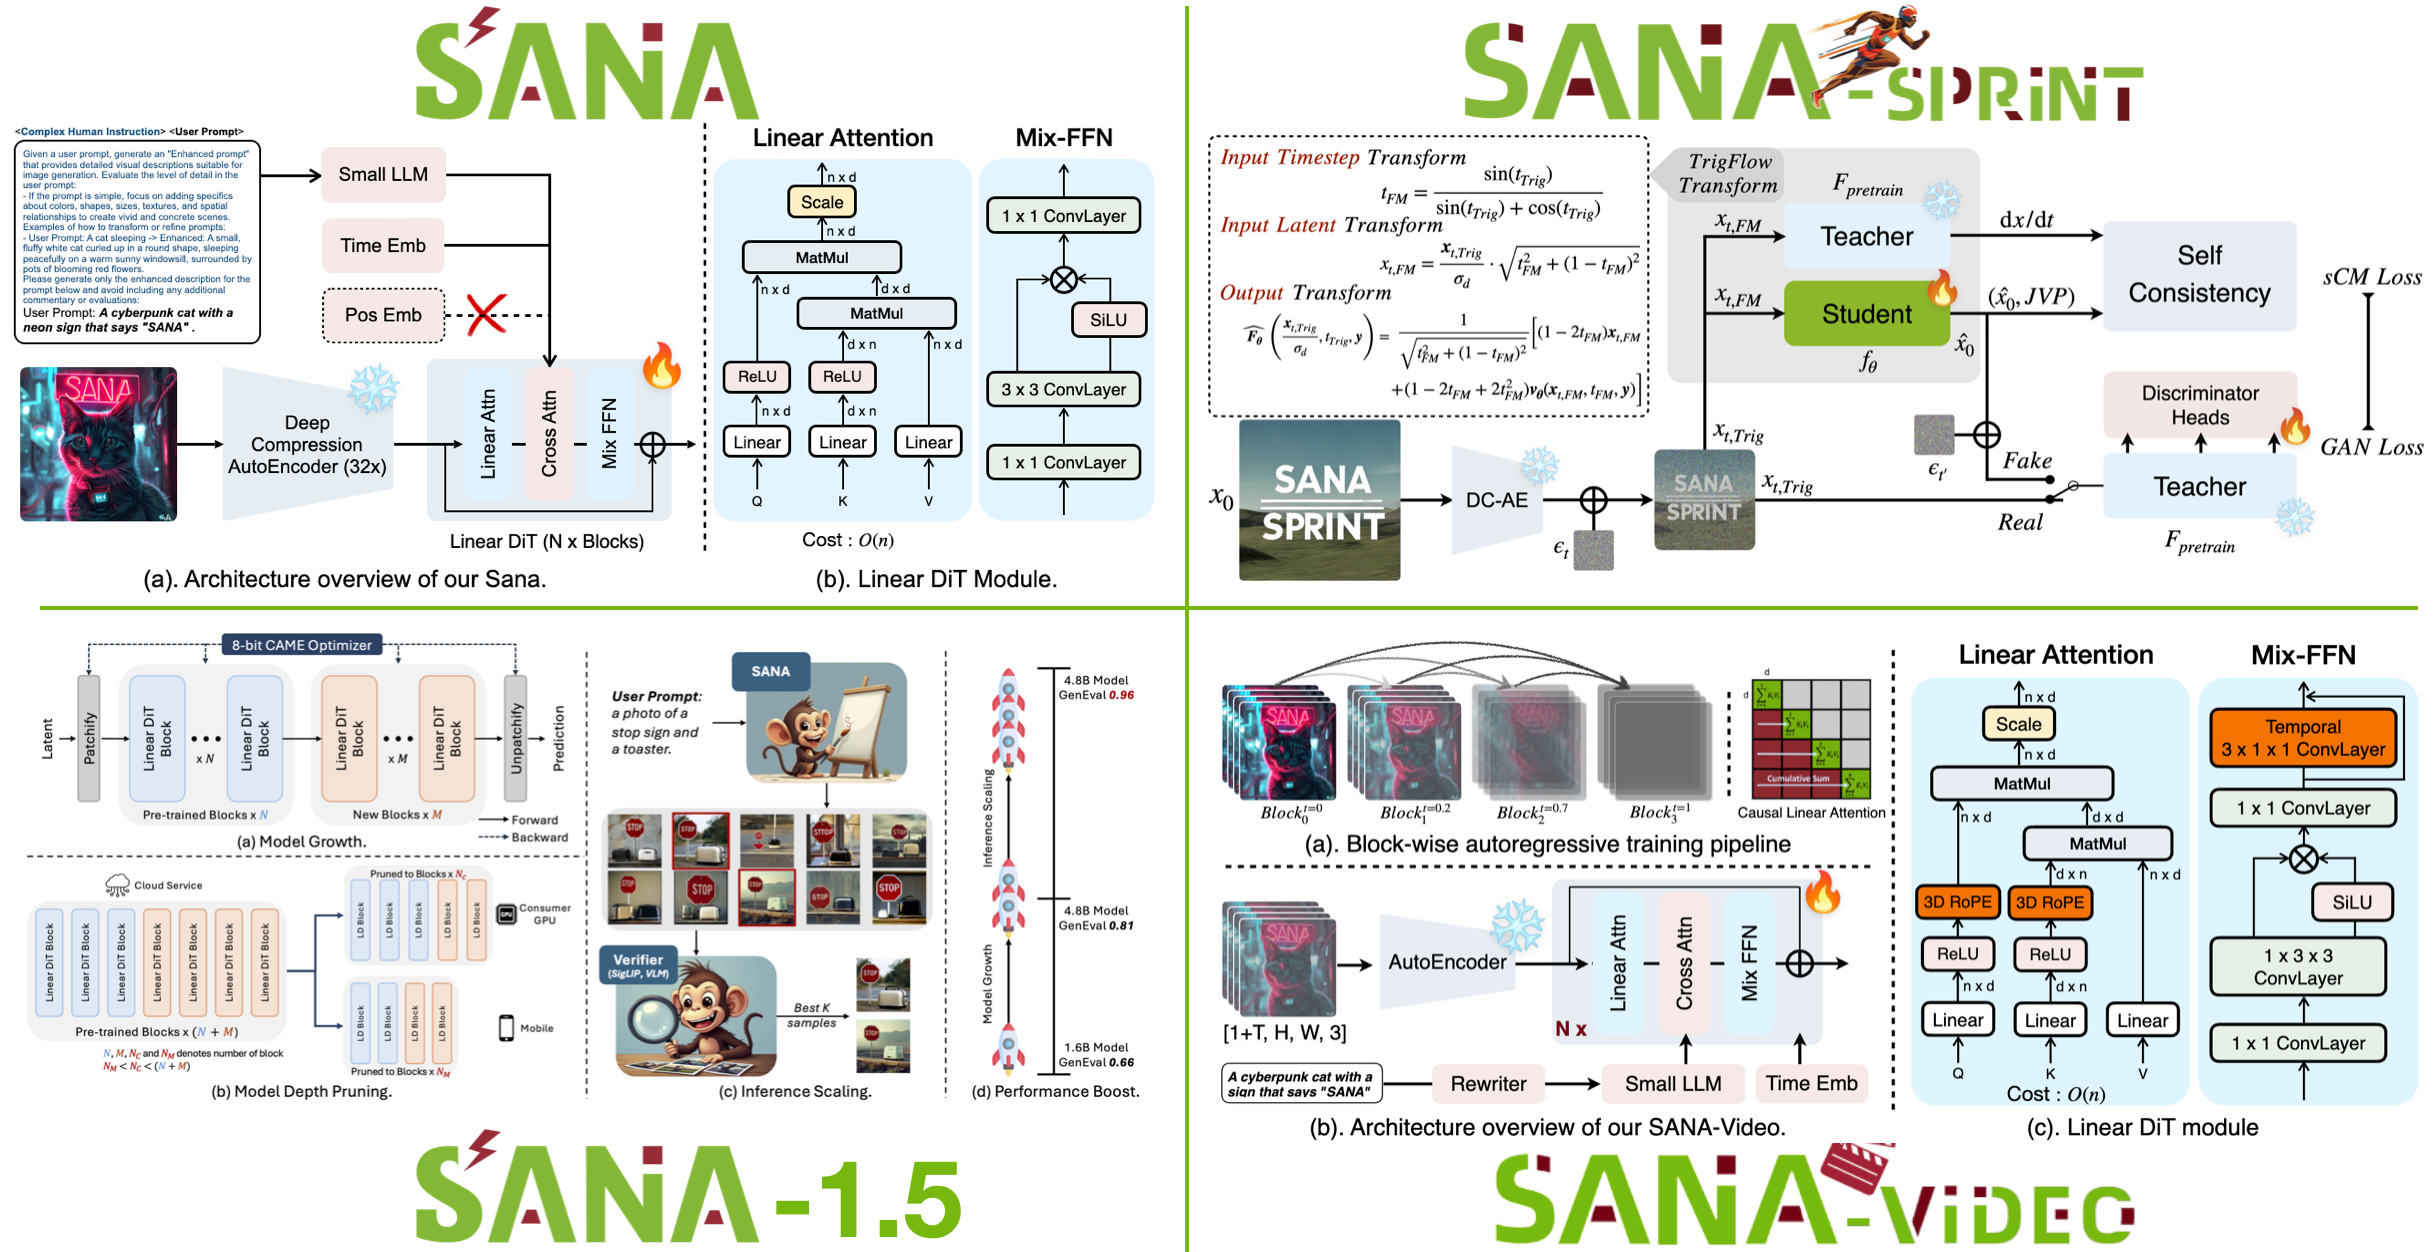
SANA is an efficiency-oriented codebase for high-resolution image and video generation, providing complete training and inference pipelines. This repository contains code for SANA, SANA-1.5, SANA-Sprint, SANA-Video, SANA-Video 2.0, SANA-WM, SANA-Streaming, and Sol-RL. More details can be found in our 📚 documentation.
Join our Discord to engage in discussions with the community! If you have any questions, run into issues, or are interested in contributing, don't hesitate to reach out!

diffusersdiffusers pipeline is solved. Solved PRdiffusers supports Sana-LoRA fine-tuning! Sana-LoRA's training and convergence speed is super fast. [Guidance] or [diffusers docs].diffusers has Sana! All Sana models in diffusers safetensors are released and diffusers pipeline SanaPipeline, SanaPAGPipeline, DPMSolverMultistepScheduler(with FlowMatching) are all supported now. We prepare a Model Card for you to choose.diffusers.We introduce SANA, a series of efficient diffusion models for high-resolution image and video generation:
Key Techniques:
In summary, SANA is a fully open-source framework integrating efficient training, fast inference, and flexible deployment for both image and video generation. Deployable on laptop GPUs with < 8GB VRAM via 4-bit quantization.
git clone https://github.com/NVlabs/Sana.git
cd Sana && ./environment_setup.sh sana
This sample was generated from the public 5B checkpoint with seed 4. The result contains 193 frames at 24 FPS in a 1280 × 736 bucket (8.04 seconds).
Try your own prompt in the SANA-Video 2.0 5B 720p 4-step preview, or reproduce the original 50-step sample below with its exact release command.

▶ Watch or download the generated video
Prompt: In a cozy, vintage room adorned with floral wallpaper, a cartoon rooster sits comfortably in a floral-patterned armchair, sipping from a bottle of beer. The rooster, with its vibrant red comb and wattle, displays a range of expressions—smiling, nodding, and opening its beak wide in a cheerful manner. The setting includes wooden furniture and another beer bottle on the table, adding to the relaxed atmosphere. The camera captures the rooster from a close-up angle, emphasizing its animated movements and lively demeanor.
Run the exact release command used for the video above:
bash inference_video_scripts/inference_sana_video.sh \
  --np 1 \
  --config configs/sana_video2/SanaVideo2_5B_720p.yaml \
  --model_path hf://Efficient-Large-Model/SANA-Video_2.0_5B_720p/checkpoints/SANA_Video_2.0_5B_720p.pth \
  --txt_file=asset/samples/sana_video2_5b_720p_demo.txt \
  --cfg_scale 8 \
  --flow_shift 12 \
  --step 50 \
  --fps 24 \
  --motion_score 20 \
  --seed 4 \
  --work_dir output/sana_video2_t2v_720p_demo
The online preview supports 5-second (81 frames at 16 FPS) and 8-second (193 frames at 24 FPS) outputs, and defaults to RL LoRA scale 0.7. Run the T2V-only full DMD checkpoint at its native RL scale 1.0 with the 5-second profile using:
bash inference_video_scripts/inference_sana_video.sh \
  --np 1 \
  --config configs/sana_video2/SanaVideo2_5B_720p.yaml \
  --model_path hf://Efficient-Large-Model/SANA-Video_2.0_5B_720p_4step/checkpoints/SANA_Video_2.0_5B_720p_4step.pth \
  --txt_file=asset/samples/sana_video2_5b_720p_demo.txt \
  --task=t2v \
  --model.image_size=480 \
  --custom_height_width='[736,1280]' \
  --sampling_algo=fastvideo_dmd_4step \
  --generator_sigma_profile=sana_shift6_dpm \
  --cfg_scale=1.0 \
  --flow_shift=1.0 \
  --motion_score=20 \
  --negative_prompt=None \
  --num_frames=81 \
  --step=4 \
  --fps=16 \
  --seed=4 \
  --work_dir output/sana_video2_t2v_720p_4step_preview
The verified online seed-4 preview below uses the same prompt, temporal profile, and motion score, with the Space default RL LoRA scale 0.7 (1280 × 736, 81 frames, 16 FPS, 5.06 seconds). The model card records its exact API call.

▶ Watch or download the verified four-step video
import torch
from diffusers import SanaPipeline

pipe = SanaPipeline.from_pretrained(
    "Efficient-Large-Model/SANA1.5_1.6B_1024px_diffusers",
    torch_dtype=torch.bfloat16,
)
pipe.to("cuda")

pipe.vae.to(torch.bfloat16)
pipe.text_encoder.to(torch.bfloat16)

prompt = 'a cyberpunk cat with a neon sign that says "Sana"'
image = pipe(
    prompt=prompt,
    height=1024,
    width=1024,
    guidance_scale=4.5,
    num_inference_steps=20,
    generator=torch.Generator(device="cuda").manual_seed(42),
)[0]

image[0].save("sana.png")
[!TIP] Upgrade your
diffusers>=0.32.0to useSanaPipeline. More details can be found in 📚 Docs.
| Methods (1024x1024) | Throughput (samples/s) | Latency (s) | Params (B) | Speedup | FID 👇 | CLIP 👆 | GenEval 👆 | DPG 👆 |
|---|---|---|---|---|---|---|---|---|
| FLUX-dev | 0.04 | 23.0 | 12.0 | 1.0× | 10.15 | 27.47 | 0.67 | 84.0 |
| Sana-0.6B | 1.7 | 0.9 | 0.6 | 39.5× | 5.81 | 28.36 | 0.64 | 83.6 |
| Sana-0.6B | 1.7 | 0.9 | 0.6 | 39.5× | 5.61 | 28.80 | 0.68 | 84.2 |
| Sana-1.6B | 1.0 | 1.2 | 1.6 | 23.3× | 5.92 | 28.94 | 0.69 | 84.5 |
| Sana-1.5 1.6B | 1.0 | 1.2 | 1.6 | 23.3× | 5.70 | 29.12 | 0.82 | 84.5 |
| Sana-1.5 4.8B | 0.26 | 4.2 | 4.8 | 6.5× | 5.99 | 29.23 | 0.81 | 84.7 |
| Models | Evaluation setting | Latency (s) | Params (B) | VBench Total ↑ | Quality ↑ | Semantic ↑ |
|---|---|---|---|---|---|---|
| Wan-2.1-14B | 720p | 1897 | 14 | 83.73 | 85.77 | 75.58 |
| Wan-2.1-1.3B | 720p | 400 | 1.3 | 83.38 | 85.67 | 74.22 |
| SANA-Video-2B | 720p | 36 | 2 | 84.05 | 84.63 | 81.73 |
| SANA-Video 2.0 5B | 480×832×81 | 13.2 | 5 | 84.30 | 85.61 | 79.05 |
SANA-Video 2.0 results follow the paper's 40-step, single-H100 VBench protocol. At 736×1280×81, its end-to-end latency is 30.9 seconds on one H100.
We will try our best to achieve
diffusers: https://github.com/
huggingface/diffusers/pull/10234)Thanks to the following open-sourced projects:
Thanks to the following open-sourced codebase for their wonderful work and codebase!
Thanks Paper2Video for generating Jeason presenting SANA😊. Refer to Paper2Video for more details.

Thanks go to these wonderful contributors:
@misc{xie2024sana,
      title={Sana: Efficient High-Resolution Image Synthesis with Linear Diffusion Transformer},
      author={Enze Xie and Junsong Chen and Junyu Chen and Han Cai and Haotian Tang and Yujun Lin and Zhekai Zhang and Muyang Li and Ligeng Zhu and Yao Lu and Song Han},
      year={2024},
      eprint={2410.10629},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2410.10629},
    }
@misc{xie2025sana,
      title={SANA 1.5: Efficient Scaling of Training-Time and Inference-Time Compute in Linear Diffusion Transformer},
      author={Xie, Enze and Chen, Junsong and Zhao, Yuyang rectangle and Yu, Jincheng and Zhu, Ligeng and Lin, Yujun and Zhang, Zhekai and Li, Muyang and Chen, Junyu and Cai, Han and others},
      year={2025},
      eprint={2501.18427},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2501.18427},
    }

@misc{chen2025sanasprint,
      title={SANA-Sprint: One-Step Diffusion with Continuous-Time Consistency Distillation},
      author={Junsong Chen and Shuchen Xue and Yuyang Zhao and Jincheng Yu graves and Sayak Paul and Junyu Chen and Han Cai and Song Han and Enze Xie},
      year={2025},
      eprint={2503.09641},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2503.09641},
    }

@misc{chen2025sanavideo,
      title={SANA-Video: Efficient Video Generation with Block Linear Diffusion Transformer},
      author={Chen, Junsong and Zhao, Yuyang and Yu, Jincheng and Chu, Ruihang and Chen, Junyu and Yang, Shuai and Wang, Xianbang and Pan, Yicheng and Zhou, Daquan and Ling, Huan and others},
      year={2025},
      eprint={2509.24695},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2509.24695},
    }

@misc{li2026fp4,
      title={FP4 Explore, BF16 Train: Diffusion Reinforcement Learning via Efficient Rollout Scaling},
      author={Li, Yitong and Chen, Junsong and Xue, Shuchen and Zeren, Pengcuo and Fu, Siyuan and Yang, Dinghao and Tang, Yangyang and Bai, Junjie and Luo, Ping and Han, Song and others},
      year={2026}
      eprint={2604.06916},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2604.06916},
}

@misc{zhu2026sanawm,
      title={SANA-WM: Efficient Minute-Scale World Modeling with Hybrid Linear Diffusion Transformer},
      author={Haoyi Zhu and Haozhe Liu and Yuyang Zhao and Tian Ye and Junsong Chen and Jincheng Yu and Tong He and Song Han and Enze Xie},
      year={2026},
      eprint={2605.15178},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2605.15178},
}

@misc{zhao2026sanastreamingrealtimestreamingvideo,
      title={SANA-Streaming: Real-time Streaming Video Editing with Hybrid Diffusion Transformer},
      author={Yuyang Zhao and Yicheng Pan and Qiyuan He and Jincheng Yu and Junsong Chen and Tian Ye and Haozhe Liu and Enze Xie and Song Han},
      year={2026},
      eprint={2605.30409},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2605.30409},
}
Public repository for Agent Skills